How to Win a Slot in AI Assistants' 3–8 Product Picks for Marketers
A practical playbook for marketers and e-commerce teams to get products into AI assistants' shortlists. Learn which data, trust signals, and fixes win the...
· 10 min read
AI assistants pick products through a two-stage process: first they build a shortlist by filtering out anything that fails hard constraints like budget or use case, then they rank what's left by confidence, weighted heavily toward products with clean structured data and consistent third-party proof. The winners at each stage rarely overlap with what wins traditional search. Intent modeling, not keyword matching, drives both stages.
TL;DR:
- Products lacking explicit, machine-readable data such as price, category, or specs are filtered out before ranking, reducing visible options significantly.
- Confidence scores for rankings depend heavily on structured data quality, multi-platform review consistency, and verification of claims across independent sources.
- The number of recommendations shown typically ranges from three to eight, prioritizing confident, corroborated suggestions over sheer quantity.
- Shifts in AI model updates can cause sudden changes in which products are recommended, making regular data audits and diversified proof essential.
- Improving structured data, cross-channel consistency, and measurable specifications are crucial steps to increase AI visibility and recommendation success.
Table of Contents
- How AI Assistants Decide Which Products to Recommend at the Consideration Stage
- Ranking the Shortlist: Confidence, Trust Signals, and Why Lists Stay Short
- Why Generative Recommendation Models Change the Rules
- What Brands Can Do to Enter AI Consideration Sets
- Why Your AI Visibility Can Shift Overnight
- Measuring AI Recommendation Visibility, Not Just Guessing at It
- What Marketing Teams Should Fix First
- Get a Clear Picture of Your AI Recommendation Share
- Sources
- FAQ
How AI Assistants Decide Which Products to Recommend at the Consideration Stage
Before a model ranks anything, it has to decide what even qualifies. That happens through query interpretation: turning a loose conversational request into a set of explicit filters the model can test products against.
Say a shopper asks for "a durable laptop bag for a consultant who travels weekly, under $120." The model extracts at least four constraints: durability (a material or warranty signal), use case (frequent travel), user persona (business, not student), and a hard price ceiling. Every product gets checked against those filters before ranking starts. Fail one, and the product never enters the pool that gets scored.
This is where fan-out verification comes in. Rather than trust one product page's claim of "durable," many assistants issue secondary queries, checking review sites, spec sheets, or retailer listings to confirm the claim holds up elsewhere. A single unverified adjective on a brand's own site carries little weight against that cross-check.
The practical fallout for product teams:
- Pages missing explicit price, category, or attribute data get excluded before ranking even begins, regardless of quality.
- Vague marketing language ("premium," "best-in-class") without measurable specs fails the constraint-matching step.
- Products that appear only on the brand's own site, with no independent confirmation, often lose the verification pass entirely.
If your product page can't answer "what is this, who is it for, and how much does it cost" in machine-readable terms, it may never reach the stage where reviews or brand reputation even matter.
Ranking the Shortlist: Confidence, Trust Signals, and Why Lists Stay Short
Once a handful of products survive the filtering stage, the model ranks them by confidence, essentially how sure it is that a recommendation will hold up if the user checks it. That confidence score draws on several concrete signals:
- Structured data quality: schema markup, GTINs, and normalized attributes that let the model parse specs without guessing.
- Review depth and rating consistency: not just star ratings, but whether sentiment holds steady across multiple platforms.
- Third-party mentions: independent editorial coverage, comparison articles, or expert roundups that corroborate a claim.
- Cross-source consistency: matching price, availability, and specs across the brand site, retailers, and marketplaces.
Here's the part most teams miss: the model doesn't just check whether a signal exists, it checks whether the signal agrees with itself everywhere it appears. A product with glowing reviews on the brand site but no presence anywhere else scores lower than one with more moderate reviews backed by consistent listings across five retailers.
Structured, AI-ready content can achieve substantially higher visibility in generative AI responses compared to unstructured pages, according to Fast Company's reporting on how AI decides which products consumers see.
This confidence weighting also explains why AI assistants almost never hand back a list of twenty options. Most surface somewhere between three and eight, because presenting more than that undermines the appearance of a confident answer. The model isn't optimizing for coverage. It's optimizing for a defensible, tight recommendation it can support if challenged. That changes the competitive math: you're not fighting for placement on a long results page, you're fighting for one of a handful of slots where ties usually break toward whichever product has the most corroborated evidence.
Why Generative Recommendation Models Change the Rules
Older recommendation engines mostly fit patterns from historical logs: if users like you bought X, you'll probably want Y. That approach works fine for repeat purchases but struggles with genuinely new intent or products with thin purchase history.
Newer systems reframe the problem entirely. RecGPT treats recommendation as an intent-centric generative task rather than a pattern-matching exercise, and reports click-through rate improvements in production deployments. Instead of asking "what did similar users buy," it asks "what does this specific request actually mean," then generates a response built around that inferred intent.
Systems like TGR push this further with hybrid tokenization, combining semantic IDs (compressed representations of what a product is) with traditional item IDs. TGR's published results show click-through rate gains and offline slate-quality improvements, driven partly by whole-slate generation, producing the entire recommendation set at once rather than scoring items one by one.
What this means operationally:
- Grounding matters more than volume. A model reasoning about intent needs fewer, better-verified data points, not more marketing copy.
- Latency and scale trade-offs push engineers toward compressed representations like semantic IDs, which reward products with clean, structured attributes over ones described in prose.
- Signals that scale across thousands of queries (consistent structured data) beat signals that only work in isolated cases (a single glowing review).
What Brands Can Do to Enter AI Consideration Sets
Most of what determines AI visibility is fixable, and it rarely requires a new marketing budget so much as better data hygiene.
- Standardize structured data across every feed. Schema markup, GTINs, and normalized attributes should match exactly between your site, retailer feeds, and marketplaces. Inconsistency here is one of the fastest ways to get filtered out before ranking even starts.
- Build review depth deliberately. Volume matters, but consistency of sentiment across platforms matters more. A product with 40 reviews averaging 4.3 stars on three different sites outperforms one with 200 reviews on a single site.
- Avoid tags that read as paid placement. Labels that look sponsored can suppress selection probability in agent-choice evaluations, even when the underlying product is strong.
- Write for machine legibility, not just persuasion. State measurable specs, explicit use cases, and constraints (weight, dimensions, compatibility) rather than relying on adjectives.
- Audit cross-channel consistency regularly. Price mismatches or missing attributes on even one major retailer feed can quietly erode confidence scores.
Pro Tip: Start with the one data point most likely to be wrong across channels, usually price or availability, and fix that before touching anything else. Confidence scoring punishes inconsistency more than it rewards polish.
For a deeper walkthrough of these tactics, AuthorityLayer's guide on winning brand recommendations breaks down the steps by channel.
Why Your AI Visibility Can Shift Overnight
Model updates reshuffle outcomes in ways traditional SEO rarely does. A product that ranked in the top five on one assistant last month can drop out entirely after a model update changes how it weighs review recency versus review count.
That volatility isn't a bug, it's a side effect of how these systems retrain. The same optimization that performs well on one engine can underperform on another because each model weights signals slightly differently.
Practical hedges worth building into your process:
- Diversify evidence across platforms instead of concentrating proof on one channel.
- Monitor recommendation share continuously rather than checking quarterly, since shifts can happen between model updates with no public announcement.
- Prioritize fixing data inconsistencies first. They're cheaper to correct than trying to chase a moving ranking algorithm.
Measuring AI Recommendation Visibility, Not Just Guessing at It
Most brands have no idea whether they're showing up in AI-generated answers, let alone why a competitor is winning the slot instead. That's the gap AuthorityLayer's AI Visibility Intelligence approach is built to close.
The platform tracks visibility and recommendation share across assistants like ChatGPT, Gemini, Claude, and Perplexity, then benchmarks that against named competitors to show where the gaps actually sit. Instead of a scattershot list of "best practices," it flags the specific, fixable issues (a missing attribute, an inconsistent price feed, a thin review footprint) most likely to move you into the next recommendation slot.
- Prompt tracking shows which real buyer queries surface your brand and which surface competitors instead.
- Opportunity prioritization ranks fixes by expected impact, not by how easy they are to implement.
- The methodology explains exactly how each score is calculated, so nothing is a black box.
What Marketing Teams Should Fix First
Fix inconsistent product attributes before chasing reviews or press mentions. Bad data undermines everything built on top of it. Give yourself one week to run a visibility scan and see where the gaps actually are before spending on anything else.
— Geraldine
Get a Clear Picture of Your AI Recommendation Share
Most of what decides whether your product gets recommended, structured data quality, cross-channel consistency, confidence-weighted trust signals, is invisible until someone measures it directly. Guessing which fix matters most wastes budget on the wrong problem.
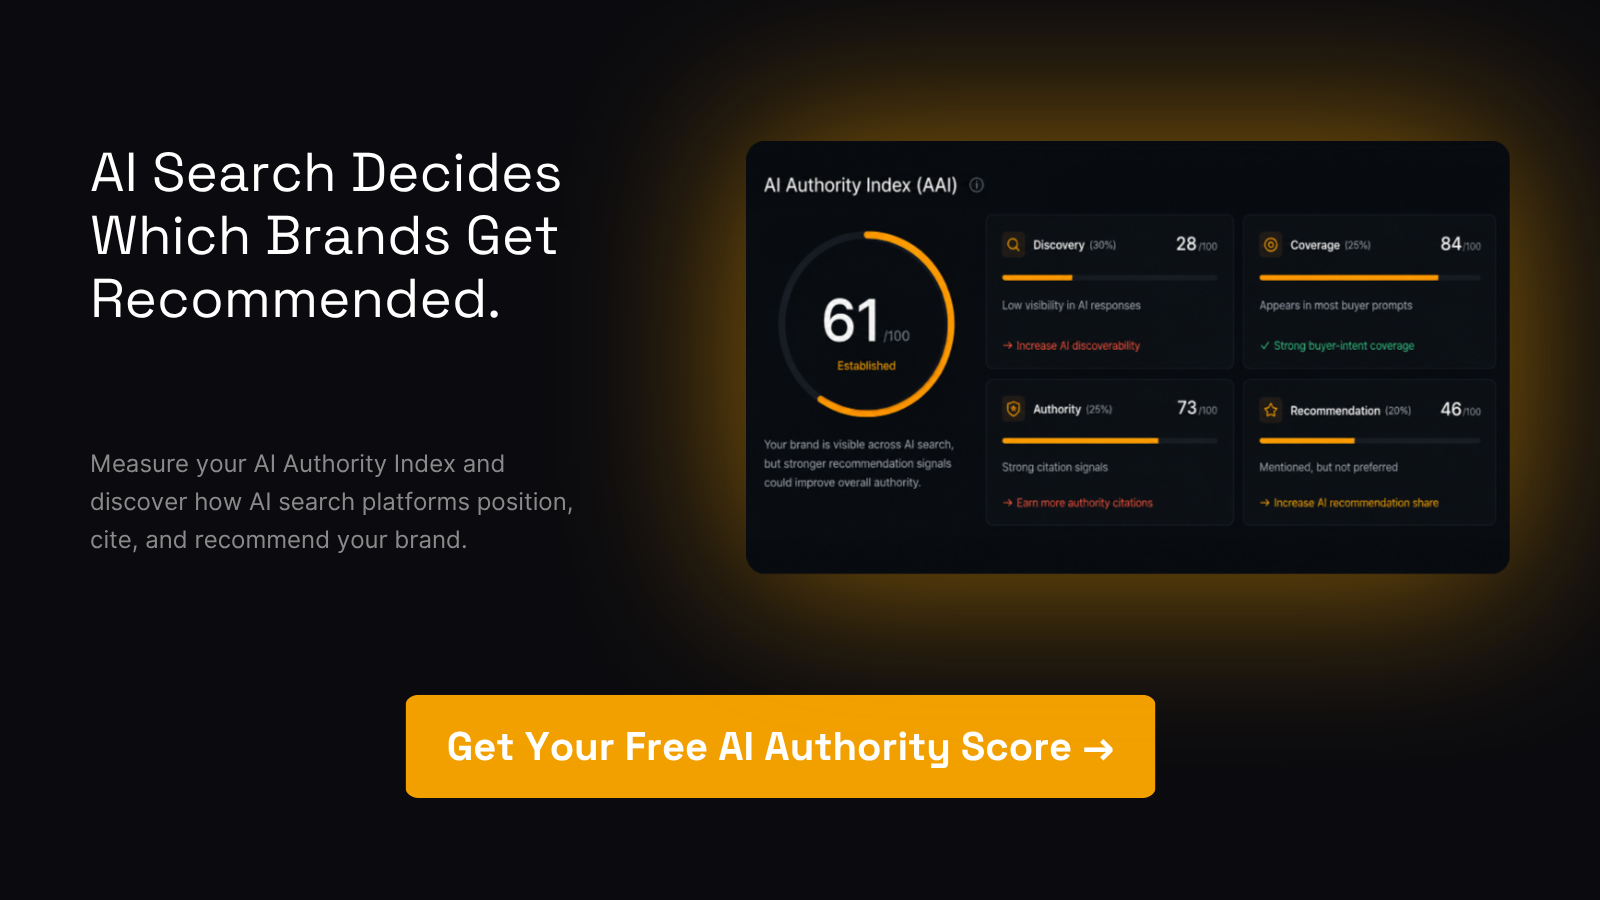
Authoritylayer's Free AI Visibility Scan shows exactly how your brand currently appears across ChatGPT, Gemini, Claude, and Perplexity, and where competitors are winning the recommendation slots you're not. From there, the Starter plan at $99 per month tracks ongoing visibility and prioritized fixes, while Growth at $349 per month adds deeper competitive benchmarking for teams managing multiple product lines. Larger organizations juggling multi-brand portfolios can look at Enterprise at $795 per month for custom coverage. If you'd rather track recommendation share over time without a full platform commitment, the Monthly AI Visibility Report at $59 per month gives a recurring snapshot. Start with the free scan and see where you actually stand before deciding what to fix.
Sources
Core claims here draw on RecGPT's production research, the TGR generative recommendation paper, Fast Company's reporting on AI product discovery, and Shopify's engineering write-up on generative recommenders. For a partner perspective on AI-driven discovery, see 121 Group's SearchInsights.Ai service.
- How AI decides which products consumers see - Fast Company
- RecGPT: A User Intent-Centric Next-Generation LLM-Powered Recommender System in Industrial Practice | ACM
FAQ
How Do You Get AI to Recommend Your Product?
Standardize structured data (schema, GTINs, normalized attributes) across every feed, build review depth that holds steady across multiple platforms, and write product descriptions with measurable specs instead of vague marketing language. Consistency across sources matters more than volume on any single channel.
Which AI Is Best for Product Recommendations?
There's no single "best" assistant since ChatGPT, Gemini, Claude, and Perplexity weight signals differently, which is why recommendation share shifts across engines. Tracking visibility across all of them, rather than optimizing for one, gives a more accurate picture of where a brand actually stands.
Which AI Is Best for Finding Products as a Shopper?
Assistants with strong fan-out verification, meaning they cross-check product claims against independent sources rather than trusting a single listing, tend to produce more reliable shortlists. Most major assistants now use some version of this verification step.
How Do You Build a Recommendation System Using AI?
Modern industrial systems like RecGPT and TGR build recommendation as an intent-centric generative task, using semantic IDs and whole-slate generation instead of simple pattern matching from purchase history. Teams building or auditing these systems need clean, structured product data as the foundation, since generative models perform only as well as the data they're grounded in.
How Much Does AuthorityLayer Cost?
Authoritylayer offers a free AI Visibility Scan to start, then paid plans at $99 per month (Starter), $349 per month (Growth), and $795 per month (Enterprise), plus a Monthly AI Visibility Report at $59 per month for ongoing tracking.